Archive·The System Design
PDF·30Stories

The System Design

An Engineering Newspaper · Curated by Adarsh Kumar

  /\_/\
 (=^.^=)
 (")_(")
				
  /\_/\
 (=^.^=)
 (")_(")
				

Source
Signal

No stories match the selected filters in today's edition.

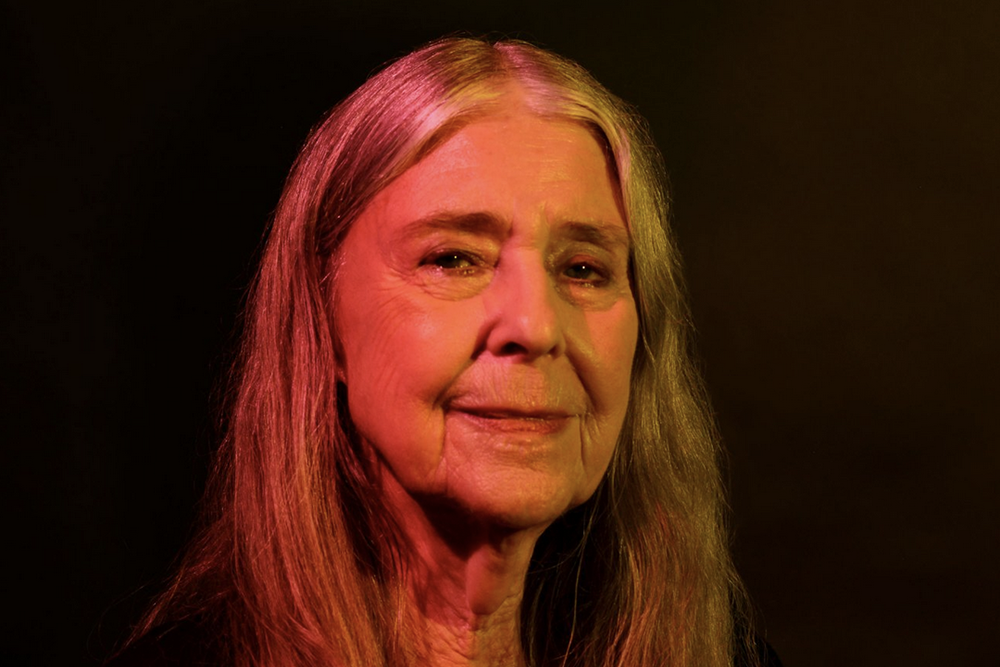
Margaret Hamilton, Who Helped Make Apollo Software Fault-Tolerant, Dies at 90

MIT News reported the death of Margaret Hamilton, whose work on Apollo flight software helped establish software engineering as a discipline. Her team designed defensive behavior for unexpected operator actions and prioritized mission-critical work when the onboard computer was overloaded.

That prioritization mattered during Apollo 11’s descent. The computer raised a 1202 alarm when lower-priority tasks competed for resources; the software shed those tasks and kept the landing work running. The spacecraft could continue without treating every overload as a total system failure.

The article also recalls an earlier simulator incident that led Hamilton to advocate for protections against an unsafe program being started in flight. Her proposed safeguard was initially rejected, then adopted after a similar action occurred during Apollo 8.

For present-day systems, the lesson is architectural: define critical work, establish priority and recovery behavior, and test failure paths before an emergency. Reliability comes from anticipating misuse and overload, not merely from adding capacity.
Anthropic Releases Claude Haiku 5.5 and Cuts Costs for Agent Work

Anthropic announced Claude Haiku 5.5 for high-volume, cost-sensitive work such as summarization, classification, database queries, and coding subagent tasks. The company says it costs about 75% less to run than Haiku 4.5 on average and is its fastest model to date.

The release adds an adjustable effort setting, letting developers trade inference cost and speed against capability. Anthropic positions Haiku for narrower, repetitive tasks, while recommending larger models for more complex agentic coding.

Alongside the model, Anthropic cut Sonnet 5.5 cache-read prices by half and began offering monthly API credits to eligible Max and Team subscribers. Its Python and TypeScript SDKs also add beta support for computer and browser use.

These are vendor-reported comparisons, so teams should benchmark their own prompts, tool loops, and failure rates. The system-design question is whether routing work to a smaller model reduces total cost without increasing retries, supervision, or downstream correction.

OpenAI published its GPT-6 announcement on October 7, presenting the release alongside an “intelligent UI for everyone.” The product framing puts the user interface next to the model itself, rather than treating interaction as a fixed chat box around a language model.

That distinction matters for product architecture. A more adaptive interface can expose generated workflows and contextual actions, but it also has to make system state, user intent, and the consequences of each action legible.

The announcement is a vendor source, so capability and availability claims should be read in that context. The practical evaluation is whether the new experience helps ordinary users complete tasks with fewer steps while preserving predictable controls.

For teams building AI products, the launch is a prompt to treat model and interface behavior as one system. Measure task completion, recovery from mistaken instructions, and the quality of human handoffs—not only benchmark scores.

Ars Technica reported that attackers obtained counterfeit TLS certificates for Google and other major services. A certificate that appears valid to a browser can let an attacker impersonate a site in a position to intercept or redirect traffic.

TLS depends on more than encryption algorithms: certificate authorities must verify that applicants control the names they request, and relying clients must correctly enforce certificate validity and revocation signals. A failure in issuance can therefore put trust in the wider certificate ecosystem at risk.

The report focuses on the certificates and the organizations involved; it does not mean every visitor to the affected services was intercepted. Exposure depends on whether an attacker could place themselves on a relevant network path and whether the certificate was accepted there.

Operators should monitor certificate-transparency logs for unexpected issuance, maintain domain-validation controls, and have a rapid revocation and key-rotation plan. The incident illustrates why trust infrastructure needs independent monitoring as well as cryptographic strength.

Docker Agent Packages Configurable AI Agents as Shareable OCI Artifacts

Docker Agent is a CLI plugin for defining and running AI agents from YAML. The project describes multi-agent delegation, built-in tools, Model Context Protocol integrations, retrieval components, and support for several hosted and local model providers.

Agent definitions can be packaged and distributed through OCI registries, bringing familiar image workflows to agent configuration. Teams can version a reusable agent, publish it, and run it in another environment without hand-copying its configuration.

The project also exposes important operational questions: model credentials, tool permissions, retrieval data, and agent memory must be governed independently of the YAML that wires them together. Docker says it collects anonymous usage data and documents its telemetry behavior.

The useful design idea is to make agent composition explicit and portable. Before adopting it, teams should test reproducibility, permissions, and failure behavior, particularly when agents can call external tools or delegate tasks to other agents.

ShinyHunters Extortion Report Connects a Boeing Divestiture to a PeopleSoft Campaign

Krebs on Security reported that ShinyHunters was extorting a business unit divested by Boeing as authorities detained a suspected group member. The report links the campaign to exploitation of an Oracle PeopleSoft vulnerability that had been used to steal data from organizations in multiple sectors.

The account describes a gap between a vendor fix and consistent protection in deployed environments. After a patch is available, internet-facing systems can remain vulnerable while owners identify affected instances, schedule changes, and verify that mitigations work.

The reporting also notes that attackers used URL-encoding techniques to bypass suggested web-application-firewall rules. That is a reminder that a WAF rule is a compensating control, not a substitute for patching a vulnerable application.

Incident response should track asset ownership through acquisitions and divestitures, maintain an inventory of exposed enterprise applications, and validate mitigations against observed attacker behavior. Long-lived business systems are often overlooked precisely because responsibility has moved between teams.

Google Playground Turns Prompts Into Shareable Experimental Games

Google introduced Playground as an experimental platform for creating, playing, and sharing custom games through prompts. Its conversational workflow is intended to let people change mechanics, characters, physics, or environments without using a conventional game engine.

The product makes generated software interactive: a user can try a result immediately and refine it through another instruction. That loop can reduce the distance between an idea and a playable prototype, while shifting complexity toward the generation and runtime layers.

The announcement describes an experiment, not a replacement for professional game tooling. Generated games still need to behave consistently, respond to edits, and avoid breaking the experience when users request changes.

For system designers, the interesting surface is the feedback loop between prompt, generated artifact, and live execution. Reliability depends on making each iteration fast and reversible, while giving users enough control to understand what the system changed.

SynthID Detector is a public-facing tool for checking whether supported media contains Google’s SynthID watermark. The detector follows the company’s earlier work embedding identifiers in AI-generated content and provides a way to inspect submitted material.

Watermark detection is a provenance signal, not a universal authenticity test. It can help identify content produced by systems that embed the mark, but the absence of a detected watermark does not prove that media is human-made or unaltered.

The reliability of such a system depends on which formats and transformations it supports, how robust the watermark remains after editing, and how clearly it communicates uncertainty. Those details matter when results are used in moderation or fact-checking workflows.

For platform designers, the launch underscores that provenance tools need careful UX: show the scope of a check, avoid treating a negative result as proof, and preserve the original file and context used for analysis.

The 11 Squares Formalized repository reports a completed Lean verification run for an optimal square-packing result. Its report says 7,920 local modules were accepted and the final audit found zero admissions.

The project is unusually explicit about its trust boundary. Selected numerical certificate checks use Lean’s native decision procedure, so the theorem depends on Lean’s kernel and native compiler rather than claiming a kernel-only proof.

The repository pins its toolchain and Mathlib revision, imports proof sources from a specified upstream commit, and publishes source, verification, and provenance details. Those controls make it possible for readers to distinguish the mathematical claim from the process used to check it.

Formal verification is strongest when its assumptions are as inspectable as its conclusion. This example offers a practical model for documenting generated certificates, dependencies, and what a successful proof run does—and does not—establish.

Bloomberg’s October 7 report examines research suggesting that AI chatbots can give shopping advice with price differences associated with a user’s apparent wealth. The finding raises a question beyond conventional product ranking: an assistant may shape which prices and options a person sees.

Personalization can make recommendations more relevant, but it also creates a less visible decision layer between a shopper and a seller. If systems infer a user’s budget or willingness to pay, the same query may produce different commercial outcomes.

The report describes a study, not proof that every chatbot or retailer dynamically sets prices for individuals. Results depend on the prompts, products, and systems tested; the underlying study and methods should be consulted before generalizing.

Designers of shopping assistants should disclose when recommendations are sponsored or personalized, preserve comparability across offers, and test for systematic differences between user profiles. Trust depends on users being able to understand why an option appeared.

musql Combines a Columnar Storage Format With JIT-Compiled SQL Execution

musql is a SQLite-compatible database project that pairs a column-oriented storage format with just-in-time compilation. Its author says supported filters and aggregates operate directly over columns, reducing row decoding and interpreter overhead.

The project reports a filtered-count benchmark roughly 300 times faster than native C SQLite and nearly 1,000 times faster than Turso. It describes a 100,000-row workload, checks results against SQLite, and notes that the timing used one thread and a direct engine API.

Those measurements are workload-specific and do not establish an advantage for every query or application. The engine also introduces a new file format and execution path, so compatibility, durability, and operational tooling matter as much as point-query speed.

The architecture is worth following because it combines embedded deployment, JIT execution, and optional replication. Teams evaluating it should run their own read/write mixes and recovery tests before treating benchmark ratios as production expectations.

PSP Web Recomp translates a decrypted PlayStation Portable executable into C++, then builds it for WebAssembly. The browser runtime also reimplements parts of the PSP operating system and graphics behavior needed by the project’s supported titles.

The project streams disc data with HTTP Range requests rather than requiring every asset to be downloaded up front. Its local server supplies the cross-origin isolation headers needed for shared-memory threading, while a single-threaded fallback supports browsers without the relevant WebGL path.

Compatibility is still narrow: the maintainers say the two working games share an engine, so they are not representative of the whole PSP catalog. Missing system calls or graphics features can stop another title from running.

The repository contains no game data, and its maintainers warn users not to publish generated game code or assets. Architecturally, it is a compact example of how binary translation, platform emulation, streaming, and browser security requirements meet in a compatibility project.

ICANN published the applications received for its 2026 round of new generic top-level domains. Its October 7 snapshot lists 1,615 applications, including 333 brand applications, 16 community-based applications, and 21 applications for internationalized domain names.

The publication also identifies contention sets, where multiple applicants seek strings that cannot all be delegated as requested. Applicants can use a replacement period from October 8 through October 21, followed by a later string-confirmation milestone.

These figures are a snapshot of primary strings, not a final count of approved domains. Every application still faces evaluation and public input, and competing applications may require resolution before any new label enters the DNS root.

The announcement is an infrastructure story as much as a branding one. New top-level domains affect registries, registrars, security monitoring, and user expectations, so the evaluation process and its public records matter beyond the applicants themselves.

Reuters reported that OpenAI says teenagers use ChatGPT for less than 15 minutes per day on average, as concerns about risks to younger users grow. The figure is the company’s characterization of usage, rather than an independent measurement of all teen AI activity.

An average can obscure the distribution beneath it: a small group of heavy users, differences between age groups, or time spent across multiple services may not appear in a single headline metric. The number also does not, by itself, measure the quality or safety of an interaction.

Usage data can inform product decisions, but safety evaluations need additional signals such as the types of conversations, escalation paths, and the effectiveness of age-appropriate safeguards. Clear definitions of the population and measurement period are essential.

For product teams, the report is a reminder to avoid using engagement time as a proxy for wellbeing. Responsible systems need to assess outcomes and risks directly, especially when users may rely on an assistant for sensitive advice.

GitHub reported an October 7 incident affecting Git operations, pull requests, and Actions. The disruption began at 15:14 UTC, with the status page reporting recovery and mitigation before marking the incident resolved at 16:25 UTC.

The incident updates distinguish mitigation from full recovery: GitHub first said degradation was mitigated, then reported services stable while it investigated the disruption. That staged communication gives customers a clearer picture than a single “back up” notice.

The status page had not yet published a detailed root-cause analysis when the incident closed. It therefore confirms the impact and timeline, but does not establish why the failure occurred or what long-term preventive changes will follow.

For engineering teams, this is a useful reminder to model dependencies across developer workflows. A brief interruption can affect source control, review, and CI at once, so incident dashboards should identify component impact and update customers as confidence changes.

The FM-1 reverse-engineering repository documents firmware analysis for the M-VAVE pocket synthesizer. Its authors identify the target as a JieLi AC791N/WL82 system with a pi32v2 CPU and trace an embedded six-operator FM engine derived from Dexed/msfa.

The project publishes disassembly, function maps, an analysis database, and tooling for examining the device’s update protocol. It explicitly distinguishes evidence about the existing updater from an established recovery or rollback mechanism.

That distinction is important for embedded research: understanding a firmware package does not prove that a device can recover from an interrupted write or accept a replacement image safely. The repository warns against treating its update protocol work as a demonstrated recovery path.

For maintainers, the work offers a reproducible analysis trail with multiple independent pipelines and pinned reference inputs. For owners, it is a caution to avoid flashing experiments until single-bank behavior and recovery options are actually established.

EmDash Uses Cloudflare Clef to Review Text and Images in Its Plugin Registry

EmDash says its plugin registry now uses Cloudflare’s Clef decision model to assess listing text, links, icons, and screenshots. The registry is built on AT Protocol, where authors publish signed releases from their own accounts while EmDash controls what appears in its discovery catalog.

The labeler asks bounded questions about scams, phishing, impersonation, offensive content, and attempts to manipulate moderation. A probability at or above the project’s 0.45 threshold sends a listing to an operator; the model does not make the final blocking decision.

EmDash reports that Clef passed its public fixture runs and live-listing evaluations, with text moderation latency of 1.64 seconds at p95 in its tests. Those results come from the project’s own evaluation set and should not be generalized to other content or workloads.

The system design combines automated triage with human review while preserving signed releases. This can make an open publishing model easier to moderate, provided thresholds, evaluation coverage, and appeal paths remain visible and accountable.

Pinrail Gives Coding Agents a Local Inbox for Human Decisions

Pinrail is a desktop application where coding agents submit a review request before taking specified actions. A review can show a code diff, generated images, or another structured payload, and the human’s decision and notes are returned to the waiting agent.

The project supports any agent able to run a command and keeps its API, reviews, and decisions on the local machine. Its documentation says the service binds to loopback, avoiding the need to expose a review endpoint to a network.

Structured approval can be safer than asking for a decision in a long conversational transcript. The agent receives explicit accepted and rejected items, while the user can leave actionable reasons for another round.

Pinrail is in early development and supports macOS and Linux, with Windows support described as upcoming. The design question it raises is valuable: define consequential steps up front and build a review surface around each action, not just around code generation.

Criteo Engineers Argue That AI Cannot Replace Junior Developers’ Learning Work

Criteo engineer Elise Baturone argues that junior developers need more than code output to become effective engineers. Debugging, asking precise questions, understanding a codebase, and explaining trade-offs are skills developed through participation in real work.

AI coding tools can accelerate routine implementation, but they may also hide the reasoning steps that help less experienced developers build a mental model. If a team delegates every small task to an assistant, it can reduce the opportunities through which new engineers learn to diagnose failures.

The article is a practitioner perspective rather than a controlled study. Its value is in surfacing a management question: how should teams structure review, pairing, and task ownership when assistants change the entry-level work available?

Organizations can make the trade-off explicit by asking juniors to explain generated changes, own debugging, and rotate through design and operational tasks. Faster code production should not come at the cost of a weaker pipeline for future technical judgment.

Shaders Packages WebGPU Effects as Components Across Front-End Frameworks

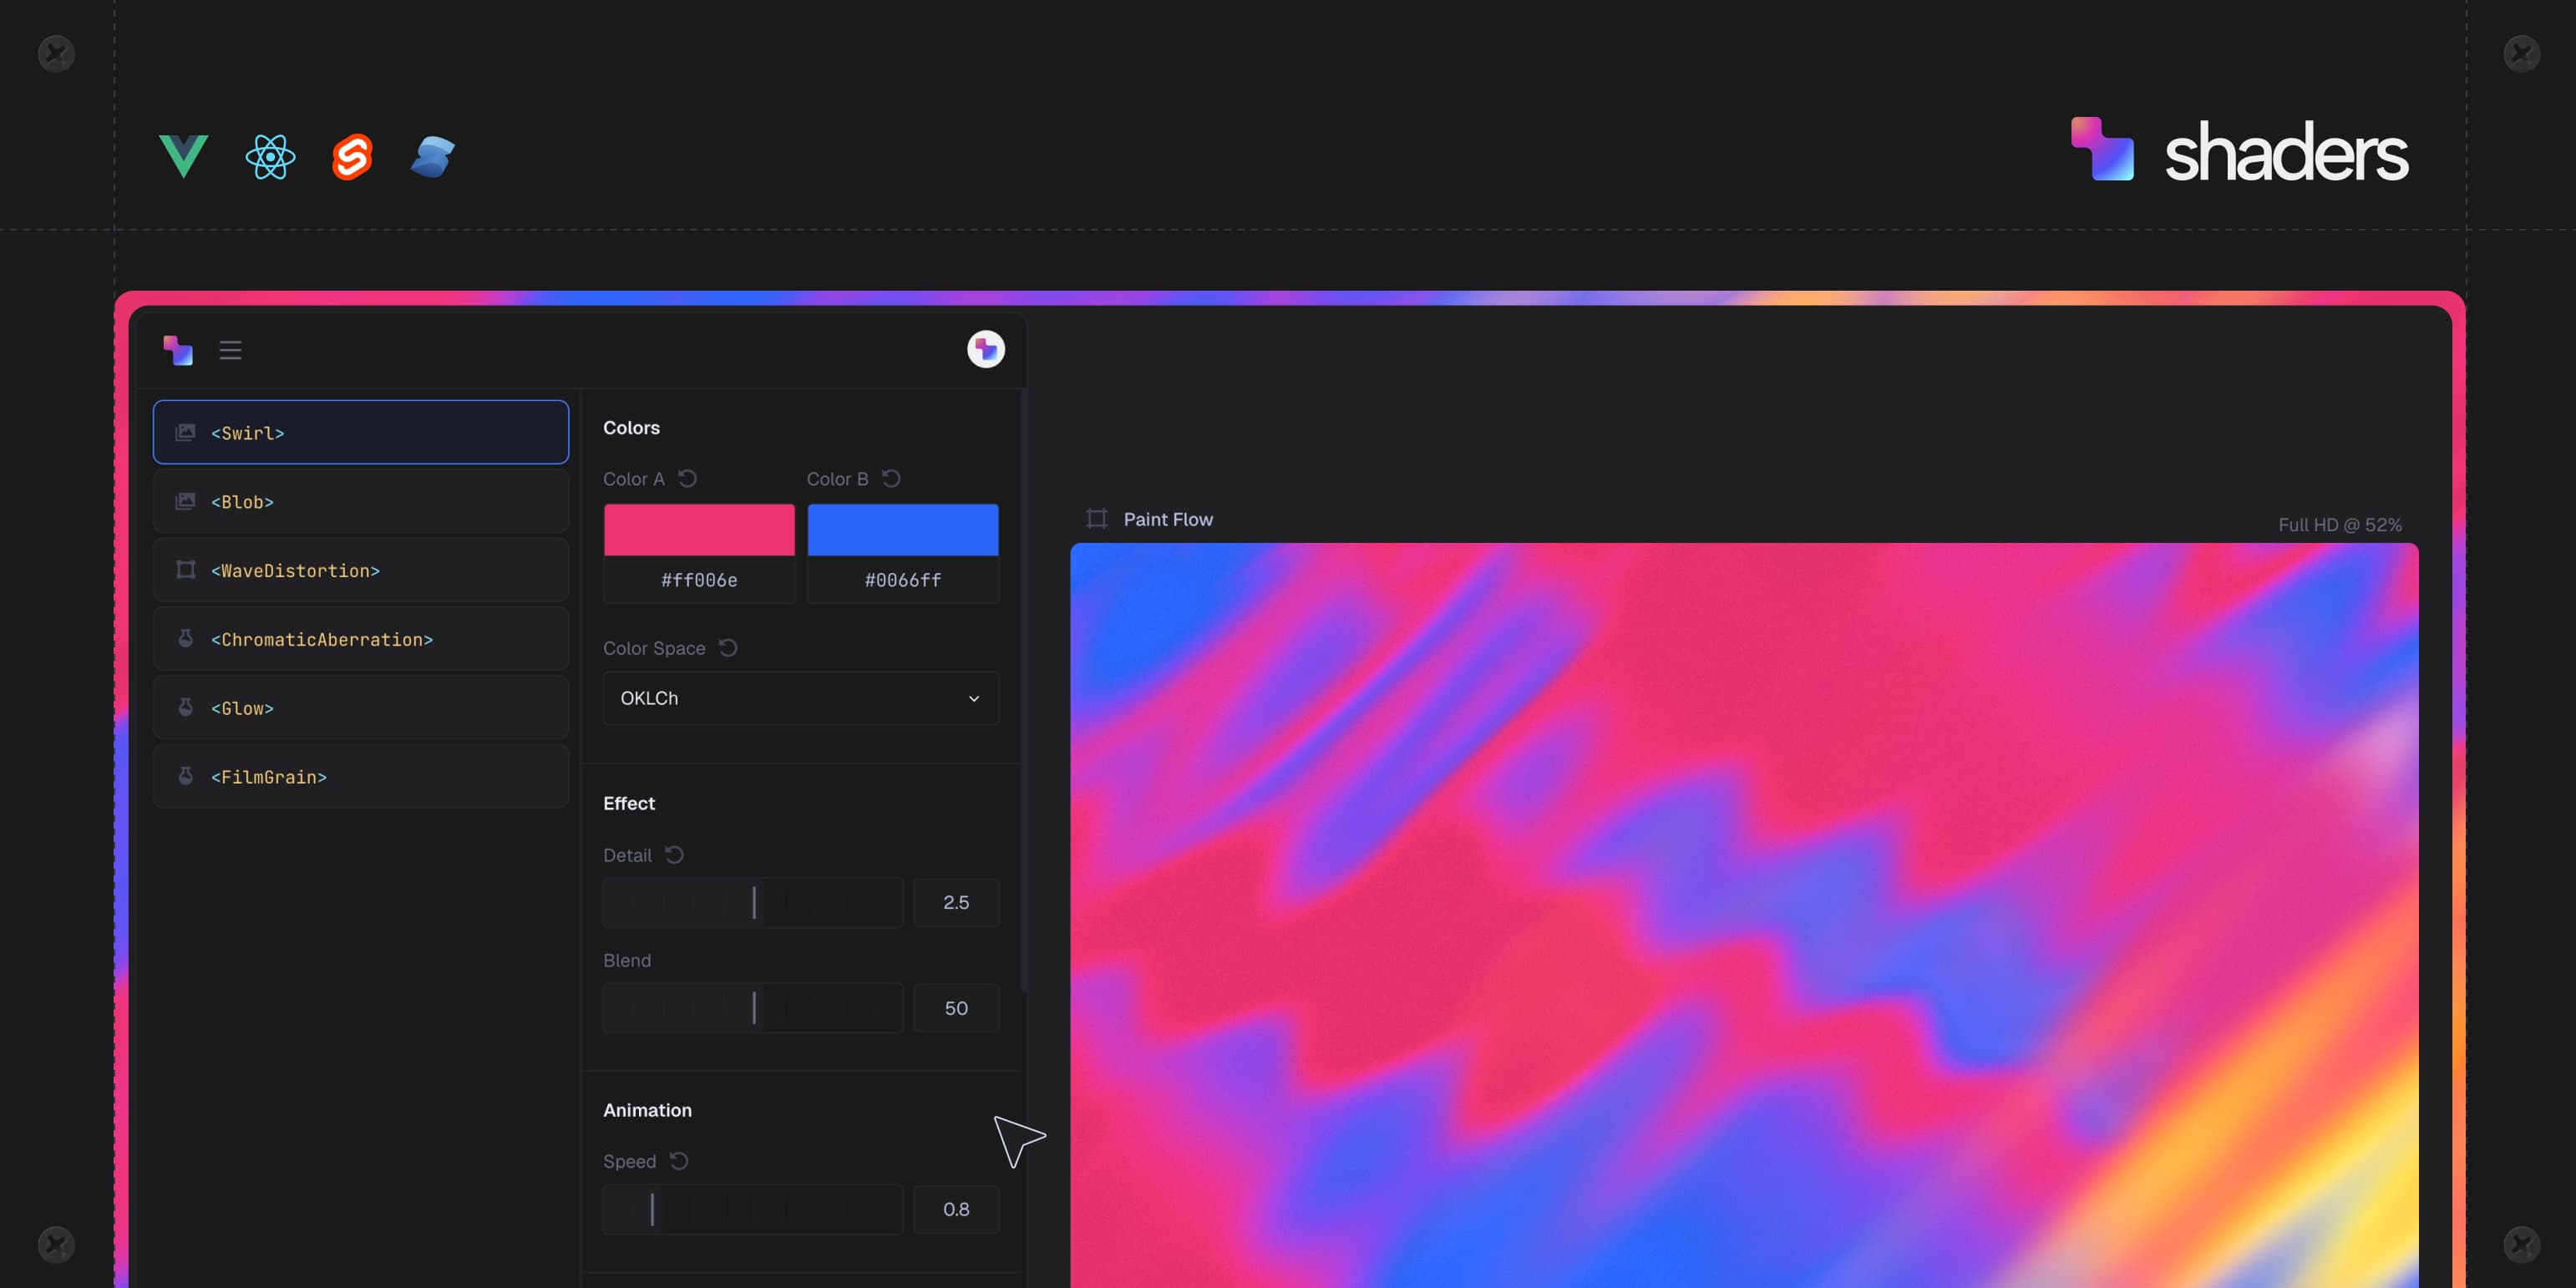
Shaders presents more than 200 WebGPU effects as composable components for React, Vue, Svelte, Solid, and plain JavaScript. The same declarative building blocks can be nested, blended, and combined to create gradients, transitions, distortions, and other visual effects.

The project pairs the component library with a visual editor that exports a framework-specific component tree. That design connects a creative workflow to application code instead of keeping the finished effect locked in a separate design tool.

GPU-backed UI still has deployment constraints: browsers need compatible hardware and APIs, and teams must consider fallbacks, rendering cost, and server-side rendering. The project describes itself as optimized and SSR-safe, claims that should be validated against each product’s supported devices.

The broader pattern is a domain-specific layer over a low-level platform API. It can make graphics more accessible, but production teams should measure frame stability and memory use on modest devices as well as desktop development hardware.

DuckLake is an open lakehouse format built around SQL metadata and Parquet data files. The DuckDB extension can attach a DuckLake catalog so users read and write tables through familiar SQL rather than managing files and metadata by hand.

The project demonstrates versioned reads, schema changes, and table-change queries in its examples. Its architecture separates catalog metadata from columnar data, allowing DuckDB to work with different catalog database choices.

The format’s operational behavior depends on more than the Parquet files: catalog consistency, concurrent writes, snapshot retention, and recovery all affect whether a lakehouse is dependable. The repository includes tests for several catalog backends and conflict behavior.

For teams evaluating open table formats, DuckLake is an example of bringing database semantics to object-storage data. Benchmark and failure-test the full catalog-plus-filesystem stack rather than evaluating file scans alone.

The Verge reported on Amazon’s “About You” shopping-preferences page after users shared unexpectedly specific descriptions inferred from their purchases. The page lets account holders see a list of details Amazon may use to personalize their experience and edit or remove them.

Personalization systems turn behavior into attributes, but users often cannot tell what was inferred or how it affects recommendations. Making the profile inspectable provides a concrete interface for understanding that hidden layer.

The examples also show why inferred data can feel intrusive even when it is technically derived from ordinary purchase history. A system can be accurate in broad strokes and still produce an embarrassing, overconfident, or unwanted characterization.

For product designers, transparency works best when paired with meaningful controls and explanations of downstream use. Users should be able to correct a profile, understand whether changes affect recommendations, and distinguish observed facts from inferred traits.

Yggstore is an experimental project for pooling storage across machines connected through the Yggdrasil overlay network. It describes splitting files into encrypted pieces and distributing them across member-operated nodes, with no central coordinator.

The project also describes mail, messaging, websites, and an S3 gateway. Its design aims to keep each node from reading other members’ stored content and uses storage challenges to check whether peers still retain assigned shards.

The author explicitly warns that the cryptography has not received independent review and says users should not make the system the only copy of important data. Those caveats are essential: decentralization and encryption do not by themselves establish durability or security.

For distributed-systems readers, the project is a useful design study in membership, replication, repair, and trust boundaries. Its experimental status makes it appropriate for evaluation—not production reliance without independent security and recovery testing.

ProcInSh Lets Linux Users Explore Processes Through a 3D Web Inspector

ProcInSh is a web-based process inspector for Linux that presents process space as an explorable 3D environment. It combines a browser interface with native code and eBPF-related tooling to expose process details on supported x86-64 systems.

The project requires elevated capabilities or sudo for some operations. Its documentation specifically warns that enabling non-loopback access exposes process memory and environment variables without authentication.

That warning is central to its deployment model: a local diagnostics tool can become a sensitive remote service if bound to an accessible interface. Process metadata may contain credentials, tokens, or other private values even when the tool is intended only for visualization.

Use it as a local inspection aid, keep the listener on loopback, and understand the privileges granted before running it. The project is also a reminder that richer observability can increase the security impact of the observability endpoint itself.

Bigwords.page turns a browser screen into a large-format sign, automatically sizing text to fit devices from phones to displays. Its feature set includes Markdown, timed slides, countdowns, QR codes, and browser-generated images.

The project stores the message in the URL fragment, which browsers do not send as part of the HTTP request. That design avoids sending the content to the hosting server, though anyone who receives the full link can still read the fragment.

Keeping rendering in the browser also avoids third-party services for generating QR codes and images, according to the project. The trade-off is that a long or sensitive message remains present in browser history, copied links, and any channel where the URL is shared.

This is a compact example of privacy-aware product design: choose where data lives, state the boundary plainly, and account for how links are handled by users. The same pattern can be useful for lightweight, ephemeral web tools.

Michael Lynch applies the idea of software anti-patterns to technical blogging, beginning with introductions that meander before explaining what a reader will gain. His central advice is to make the intended audience and payoff clear early.

The post also warns against assuming readers share the author’s background. A tutorial that relies on unexplained jargon can lose the very people it intends to teach, even if its technical statements are correct.

These writing choices affect more than style: they determine whether operational knowledge, design reasoning, and debugging practices can move across a team. A clear explanation lowers the cost of onboarding and makes decisions easier to revisit later.

The article recommends treating every paragraph and preamble as part of a reader’s attention budget. For engineers documenting systems, that means stating the problem, showing the useful idea, and defining terms before relying on them.

A New C64 Font Reconstructs the Lettering Printed on Classic Keyboard Keycaps

Levente Szabadkai published a font reconstructed from photographs of a Central European Commodore 64 keyboard. It recreates the printed key legends rather than the computer’s familiar screen bitmap typeface.

The project includes TTF, OTF, and webfont builds, editable outlines, and a browser preview for the PETSCII symbols. Its documentation distinguishes the reconstructed shapes from exact photographic traces and cites a separate reference for character identities and key assignments.

That provenance makes the work more than a visual nostalgia exercise: the font records a regional keyboard layout and the details of its printed symbols. The author also documents which historical design elements are outside the project’s licensing claims.

Small preservation projects often become more useful when their source material, assumptions, and formats are documented. Here, editable glyphs and a preview make the reconstruction inspectable and practical across modern applications.

ascii.rest provides an ascii-art custom element that loads and animates a named piece in a web page. The project also offers integrations for React and Astro, along with a direct mounting API for rendering into a preformatted text element or canvas.

The element plays while visible and holds its first frame for users who prefer reduced motion. The Astro integration renders that initial frame on the server, so the page can display content before client-side scripts load.

The no-build browser path is intentionally small: include a module script and add the element with a piece name. Framework adapters let the same content fit into existing component workflows.

This project illustrates the value of progressive enhancement for visual effects. A useful fallback makes the interface available before animation starts and gives motion-sensitive users a stable representation instead of making animation mandatory.

Terse is a Claude Code plugin intended to reduce filler in an agent’s replies. Its premise is that verbose status updates and conversational framing add friction to coding workflows where users mainly need decisions, diffs, and next steps.

This is a presentation-layer intervention rather than a change to the model’s underlying reasoning. That can make the interaction feel faster, but aggressive compression risks hiding uncertainty, assumptions, or important warnings.

The best use of concise output is selective: trim repeated acknowledgements while preserving evidence, blockers, and safety-relevant context. Teams can judge the plugin by whether it improves scan time without making reviews less informative.

The project reflects a wider design challenge in agent interfaces. An assistant’s output is part of the system’s operating cost, and controlling verbosity can help—provided the signal needed for oversight remains intact.

The Interactive Web Archive presents 160 open sound-visualization experiments in one collection. The work spans different ways of mapping audio into motion and visual form, giving developers a browsable set of examples rather than a single finished application.

An archive like this is useful because interactive graphics are easier to understand when they can be run and compared. Visitors can inspect how different visual mappings respond to sound and explore the implementation choices behind each experiment.

As with any browser-based audio project, behavior can depend on device performance, browser permissions, and how audio input is handled. Those differences are part of the engineering problem, particularly when visual response needs to feel synchronized.

The collection shows how open, small experiments can function as a practical learning resource. For teams building media interfaces, it offers inspiration for separating audio analysis, rendering, and interaction into components that can be tested independently.